
Pandas 3.0: The Arrow-Native Revolution for Quantitative Finance
The Battle for a New Dawn: Quantitative New Infrastructure (Part 4) — Pandas 3.0
In the quantitative technology stack, no tool has ever been as intimately linked with quant developers as pandas. We previously paid tribute to Wes McKinney, the creator of pandas, in an article titled "The Moon and Pandas."
Today, nearly 20 years after its inception, as many question whether pandas has grown too old ("Can the old general still eat?"), another quant developer has raised the banner of its revival.
He is Patrick Hoefler, one of the most active members of the pandas 3.0 core team and a software engineer at Citadel.
After several delays, pandas 3.0 has now entered the Release Candidate (RC) phase, and the dawn is breaking. What exciting new experiences will pandas 3.0 bring to quantitative developers?
The Elephant Sits Upright
From the first line of code written by Wes McKinney at AQR Capital Management (a leading global quantitative hedge fund) in 2008, pandas has accompanied quantitative developers for nearly two decades.
In 2008, pandas quickly became the standard for quantitative research by perfectly encapsulating the logic of Excel and SQL. It transformed dry vectorized calculations into elegant df.groupby() and df.rolling() operations. Pandas’ significance goes far beyond that of a mere software tool; in a sense, it is a "king-maker." It is precisely pandas (and later, AI) that has led Python to the pinnacle of programming languages.
However, entering the 2020s, with the influx of high-frequency data, tick-level backtesting, and trillion-dollar capital, this once-mighty "elephant" began to stumble:
- Memory "Assassin": The classic
BlockManagermechanism often causes memory usage to reach 3-10 times the size of the original data when handling mixed-type data. On a server with 128GB of RAM, processing just 20GB of tick data could trigger an Out-of-Memory (OOM) error. - Performance Bottlenecks: Due to its underlying reliance on NumPy Object types, processing string data such as contract codes and status labels is incredibly slow.
- Concurrency Desert: Limited by Python’s Global Interpreter Lock (GIL) and underlying architecture, pandas struggles to natively support multi-core parallel computing, which feels out of place in today’s era of 24-core and 32-core CPUs.
Meanwhile, tools like Polars and DuckDB, built on Rust or modern C++, have emerged as strong contenders. Unburdened by history, they directly embrace Arrow and parallelization. Facing challenges from these younger rivals, this trapped elephant must execute its most惊险 (thrilling) "turnaround."
This turnaround has been planned for a long time. The earliest date written into the core planning agenda can be traced back to the PyData Global conference in 2022.
The core of version 3.0 is not "feature iteration," but a "bottom-up architectural revolution"—migrating pandas’ internal data storage, type system, and I/O operations entirely from NumPy to Apache PyArrow, thereby resolving all historical pain points caused by NumPy.
Core Revolution: From NumPy to PyArrow
The most fundamental change in pandas 3.0 is shifting the underlying data structure from NumPy arrays to PyArrow. Although this is currently an optional enhancement in the RC version, it will become the default technical standard in quantitative practice in 2026.
Memory Layout: Columnar Storage and Cache Coherence
NumPy arrays are designed for dense numerical calculations (typically multi-dimensional), whereas PyArrow is tailored for tabular data and columnar storage.
Shifting to PyArrow brings the following improvements:
- CPU Instruction-Level Optimization: Arrow’s memory layout is "columnar" and "contiguous." In quantitative backtesting, when you calculate
df['close'].mean(), the CPU can load the entire closing price sequence into the high-speed cache at once and utilize SIMD (Single Instruction, Multiple Data) instruction sets to process multiple prices in a single clock cycle. In NumPy, due to the complexity of the BlockManager, data arrangement in memory is often not absolutely contiguous (surprisingly!). - Zero-Copy and Cross-Language Collaboration: This is the most exciting aspect for quantitative practice. Arrow is an industrial-grade memory standard. In 2026, if you write a high-frequency factor calculation engine in Rust, you can directly pass the memory address of pandas 3.0 to Rust, requiring no data copying in between. This ability for "in-place sharing" completely ends the performance bottleneck of Python in data-intensive tasks.
String Revolution: Goodbye Object, Hello Arrow String
Prior to version 3.0, string columns (contract codes, order status) were stored as Python’s Object type. Each string was an independent object in heap memory, leading to a severe performance black hole.
Why is Arrow String a Major Improvement?
Shifting from object to Arrow String represents a significant transformation in memory structure.
In the old version, a contract code column with 1 million rows stored 1 million pointers to Python String objects in memory. In version 3.0, all string content is compactly stored in one large contiguous buffer, accompanied by an offset array.
- Benchmark Comparison:
- Memory Usage: Storing 1 million 6-character codes occupies approximately 80MB in the old version, but only about 12MB in version 3.0.
- Computational Performance: Executing
df['symbol'].str.upper()is 30+ times faster in version 3.0, as it scans contiguous memory at the C level rather than processing objects one by one in the Python virtual machine.
The official release of the 3.0 RC specifically emphasizes that the string type will default to mapping to string[pyarrow]. This means you no longer need to manually convert types; the system will automatically select the most performant backend for you.
Furthermore, this backend replacement also improves CSV reading speeds. Before Pandas 3.0, reading a CSV file looked like this:
df = pd.read_csv('large_data.csv')If you didn’t like reading the documentation, you might not have known about the engine='pyarrow' parameter, which significantly boosts performance. In Pandas 3.0, you don’t need to memorize this parameter; everything is already optimally configured.
Copy-on-Write (CoW)
If you check the latest pandas 3.0.0 Whatsnew, you will find that Copy-on-Write is undoubtedly the protagonist. This is not just about performance, but also about eliminating semantic ambiguity.
In older versions, the rules for views (View) and copies (Copy) were extremely vague. This led to the notorious SettingWithCopyWarning.
# Trap in older versions
df = pd.DataFrame({"a": [1, 2], "b": [3, 4]})
subset = df.iloc[0:1]
subset.iloc[0, 0] = 100 # Did df change?When assigning a value in the third line, we can accept whether or not it changes the original df data. What we cannot accept is the uncertainty: df might change, or it might not. This introduces a Schrödinger’s cat-like joke: we can only determine if the cat is alive when we open the box.
In older versions, this depended on whether df was managed as a single block (Single Block) or multiple blocks (Multi Block). This uncertainty is a breeding ground for strategy bugs.
We certainly do not like this ambiguous state. We do quantitative trading for certainty—even if it is certainty based on probabilities.
Therefore, in some underlying quantitative frameworks (such as alphalens), you can see df.copy() used everywhere. This eliminates reference uncertainty but comes at the cost of performance.
Determinism and Security in 3.0
In version 3.0, with CoW enabled by default, the rules become exceptionally clear: Any slice or filter operation on a Dataframe is a "reference" before modification, and automatically triggers a "copy" creation upon modification.
# Behavior example in 3.0
df = pd.DataFrame({"a": [1, 2], "b": [3, 4]})
df2 = df["a"] # This is just a lightweight reference in memory, with almost zero overhead
df2.iloc[0] = 100 # Only at this line does pandas actually execute the Copy operation
# Result: df remains [1, 2], df2 becomes [100, 2]. The logic is completely intuitive.In other words, when you use a reference variable and modify its value, you will never change the original data. When you attempt to change the data of a reference variable, the variable automatically copies a副本 (copy) for itself. This is a memory-sharing technology that operating systems have used for decades.
You no longer need df.copy()!
Moving Toward Declarative Style
In the 3.0 RC, pandas introduced a new feature paying homage to Spark and Polars: pd.col().
# New syntax attempt in 3.0 RC
df.select(pd.col("price") * pd.col("volume"))This syntax allows developers to build computational logic without directly manipulating Dataframe objects. This is very useful for constructing complex factor calculation flows (Factor Pipelines), as it reduces the creation of intermediate variables and makes the code more readable. Although still in its infancy, it reveals the future evolution direction of pandas: shifting from "procedural" to "declarative."
The Behind-the-Scenes Force: Patrick Hoefler and the Obsession with CoW
If pandas 3.0 has a soul figure, then Patrick Hoefler (GitHub ID: phofl) is undoubtedly one of them.
He is one of the most active members of the pandas core team and the primary driver of the Copy-on-Write mechanism.
Patrick is an academic achiever, a graduate of the University of Oxford, and currently works at Citadel.
His work has always focused on making pandas more "deterministic." Over the past few years, he has almost single-handedly refactored the complex internal indexing logic of pandas, with the goal of eliminating the SettingWithCopyWarning that has frustrated countless beginners.
- From Complexity to Simplicity: Patrick has mentioned in multiple technical talks that while Copy-on-Write is extremely complex to implement, it brings极致 (extreme) simplicity to users—you no longer need to worry about whether your modifications will accidentally affect the original data.
- Balancing Performance and Safety: The CoW mechanism he led, through lazy copy (Lazy Copy) technology, ensures that memory overhead is minimized while guaranteeing data safety.
From Wes McKinney to Patrick Hoefler, quantitative developers have consistently contributed to the open-source community and Python.
The Late 3.0
However, the release journey of Pandas 3.0 has not been smooth. Planned in 2022, initially scheduled for July 2023, it was delayed to 2024, then 2025, and finally, the RC version has arrived late this year. Meanwhile, Polars, despite starting a year earlier, released a stable 1.0 version in 2025, moving much more lightly in comparison. One might wonder: why can’t a hot stove beat a newly built one?
History is not wealth; it is baggage.
pandas possesses the code assets of millions of quantitative researchers and data scientists worldwide. It is not painting on a blank canvas but replacing the engine of a high-speed train while it is moving.
- The Shackles of Backward Compatibility: Polars can design entirely new APIs that conform to modern logic (for example, its expression syntax has been declarative from the start). Pandas, however, must ensure that tens of millions of existing strategy scripts do not throw errors while introducing new features. This commitment to stability means that every underlying change (such as adjustments to BlockManager) requires an extremely complex deprecation cycle. Behind every warning (Warning) issued lies months of code auditing.
- The Double-Edged Sword of NumPy: NumPy was the cornerstone of pandas’ success, giving Python numerical calculation capabilities close to C. However, NumPy was primarily designed for scientific computing. It struggles with managing memory for "tabular" data (i.e., data containing different types and missing values). For instance, NumPy does not natively support missing values (NaN must be a float), leading to the long-standing awkwardness of "integer columns with nulls becoming floats."
In contrast, pandas, rushing toward the finish line of 3.0, has prepared for years to complete this thrilling leap from NumPy to PyArrow "without breaking the world." This is not just a rewrite of code, but a reshaping of community consensus.
Welcoming the King’s Return of the Elephant
After years of delay, even if Pandas 3.0 is released tonight, Polars is already a step ahead. After experiencing Polars’ extreme lightness, many may ask: why do I still need to use Pandas 3.0?
The key is not who is faster, but whose ecosystem is more powerful.
Quantitative research is not an isolated island.
Machine learning frameworks (Scikit-learn), statistical analysis tools (Statsmodels), backtesting engines (Zipline, Backtrader), and strategy evaluation libraries (Quantstats) still have pandas data formats flowing through their veins.
Although Polars can calculate quickly, when collaborating with these vast ecosystems and delivering final models, pandas remains the "official language." The significance of 3.0 lies in granting you performance close to Polars without detaching from the ecosystem’s sovereignty.
Additionally, although opinions may vary, Polars lacks indices! Even more so, multi-level indices, and the pivot table functionalities that come with them. If you frequently use multi-level indices, stack, and unstack in Pandas, you will likely remain locked into Pandas, as it is predictable that Polars will almost never add index functionality.
The RC release of pandas 3.0 marks the official entry of the Python data analysis ecosystem into the Arrow-Native Era. It is not only the nirvana of a veteran but also the ultimate foundation for quantitative developers to meet the challenges of massive data over the next decade.
When the "elephant" completes its turnaround, it may still remain the king of this forest. For quantitative developers, now is the best window for learning and migration.
Today’s Famous University
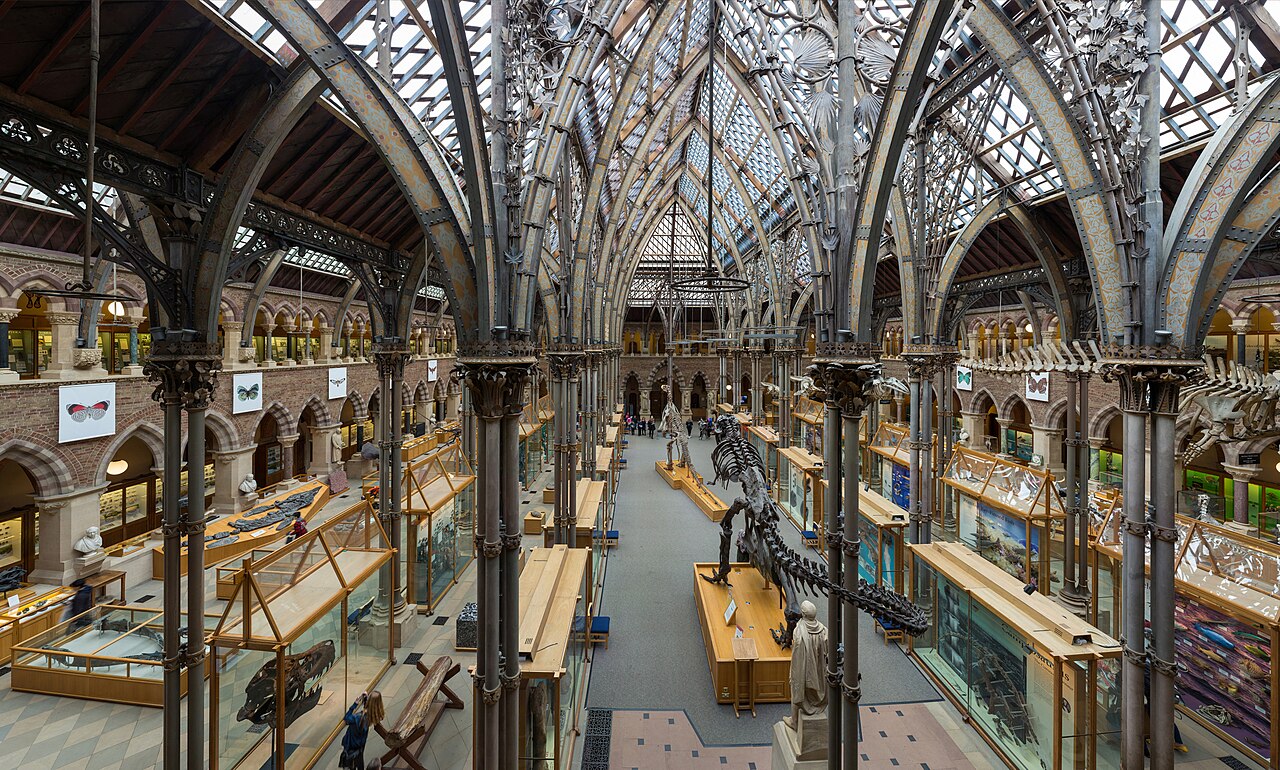
This is the Natural History Museum of a famous university. The skeleton in the image is the Megalosaurus, the first dinosaur to be scientifically named in human history.
At that time, the word "dinosaur" did not yet exist, so it was called Megalosaurus (meaning "large lizard").
Do you know which school this is?
At this school, besides Patrick Hoefler (Citadel), the following figures are also related to quantitative finance:
- Paul Wilmott: The core leader of the CQF program, author of several classic quantitative finance textbooks (such as Option Pricing: Mathematical Models and Computation).
- Álvaro Cartea: Professor of Mathematical Finance at the university, formerly at UCL and JPMorgan Chase, skilled in using machine learning to analyze financial data.
- Rama Cont: Chair Professor of Mathematical Finance at the university, recipient of the French Academy of Sciences’ "Louis Bachelier Prize" (one of the highest honors in quantitative finance).
- Jan Obloj: Professor of Mathematics at the university, focusing research on "robustness of quantitative models" (avoiding overfitting), which has a significant impact on the stability of high-frequency trading strategies. Students interested in high-frequency trading might want to look up his papers.