QuanTide Weekly: China Market Updates & Numpy Quant Techniques
This Week's Highlights
- He Lifeng meets with the U.S. delegation of the China-U.S. Economic Working Group
- Public security authorities strictly investigate capital market "rumors"; three individuals fined
- CSRC comprehensively optimizes broker risk control indicator system
- U.S. "Biosecure Act" not included in Senate 2025 FY National Defense Authorization Act
- Kweichow Moutai: Plans to repurchase shares worth RMB 3–6 billion for cancellation, first buyback plan since IPO
Next Week's Watchlist
- CSI A500 Index launches on Monday. Previously, related funds were rumored to have ended fundraising early.
- 2024 Shenzhen eVTOL & Low-Altitude Economy Expo opens; First China Digital Human Conference held in Beijing.
- Wednesday and Friday mark ETF and A500 delivery days.
This Week's Selection
- Series! Numpy Programming Essentials for Quants (4)
- China-U.S. Economic Working Group Meeting: Held in Beijing on September 19–20, co-chaired by China’s Vice Minister of Finance Liao Min and U.S. Deputy Treasury Secretary Jonathan Talbott. Relevant departments from both countries attended. On the 20th, He Lifeng met with Deputy Treasury Secretary Talbott’s delegation.
- Crackdown on Market Rumors: Public security authorities recently investigated and punished a case where social media operators maliciously fabricated online rumors to attract followers and profit, disrupting social order. According to the Cybersecurity Bureau of the Ministry of Public Security, Liu (36), Chen (46), and Shao (26) intentionally fabricated and released rumors regarding securities lending and shorting to mislead the public and disrupt financial order.
- CSRC Optimizes Broker Risk Metrics: The CSRC released the Provisions on the Calculation Standards for Risk Control Indicators of Securities Companies. Industry insiders note this is expected to release nearly 100 billion RMB in capital, improving capital efficiency and enhancing support for the real economy and wealth management.
- U.S. Biosecure Act Excluded from NDAA: On September 19, the U.S. Senate Military Committee released the Senate version of the 2025 National Defense Authorization Act (NDAA), which includes 93 amendments but excludes the "Biosecure Act." The House had previously passed an NDAA without the Biosecure Act. The Senate and House will now negotiate to merge the bills. Previously, rumors had suppressed the CXO sector.
- U.S. Stock Market: The three major U.S. indices closed with mixed results on Friday, all recording their second consecutive weekly gain. The Dow Jones Industrial Average hit new highs, up 1.61% for the week; the S&P 500 rose 1.36%; and the Nasdaq Composite gained 1.49%.
Numpy Quantitative Scenarios: Case Studies [1]
Continuous Value Statistics
In many quantitative scenarios, we need to count how many times an event has occurred consecutively, such as consecutive price limits, N-day winning streaks, or calculating streaks in Connor's RSI. For example, how do we determine the maximum number of consecutive price limits or the longest N-day winning streak in the following closing prices?
a = [15.28, 16.81, 18.49, 20.34, 21.2, 20.5,
22.37, 24.61, 27.07, 29.78, 32.76, 36.04]Assuming a 10% gain threshold, we can convert the array as follows:
pct = np.diff(a) / a[:-1]
pct > 0.1This yields the following array:
flags = [True, False, True, False, False, False, True, False, True,
True, True]This still doesn't calculate the maximum consecutive price limits, but it is a fundamental data structure for such problems. After converting raw data into such arrays based on conditions, we can use the following utility:
from numpy.typing import ArrayLike
from typing import Tuple
import numpy as np
def find_runs(x: ArrayLike) -> Tuple[np.ndarray, np.ndarray, np.ndarray]:
"""Find runs of consecutive items in an array.
Args:
x: the sequence to find runs in
Returns:
A tuple of unique values, start indices, and length of runs
"""
# ensure array
x = np.asanyarray(x)
if x.ndim != 1:
raise ValueError("only 1D array supported")
n = x.shape[0]
# handle empty array
if n == 0:
return np.array([]), np.array([]), np.array([])
else:
# find run starts
loc_run_start = np.empty(n, dtype=bool)
loc_run_start[0] = True
np.not_equal(x[:-1], x[1:], out=loc_run_start[1:])
run_starts = np.nonzero(loc_run_start)[0]
# find run values
run_values = x[loc_run_start]
# find run lengths
run_lengths = np.diff(np.append(run_starts, n))
return run_values, run_starts, run_lengths
pct = np.diff(a) / a[:-1]
v,s,l = find_runs(pct > 0.099)
(v, s, l)The output is:
(array([ True, False, True]), array([0, 3, 6]), array([3, 3, 5]))
The output is a tuple of three arrays representing:
- value: unique values
- start: start indices
- length: length of runs
In the output above, v[0] is True, indicating the start of a series of price limits. s[0] is the corresponding start index (index 0), and l[0] indicates the consecutive price limit count is 3. Similarly, we can see that the longest consecutive price limit in the original array (v[2]) is 5 (l[2]), starting from index 6 (s[2]).
To find the maximum consecutive price limit in the original sequence, we simply need to find the maximum value in l. However, solving this requires a slight trick using the mask array introduced in Chapter 4.
v_ma = np.ma.array(v, mask = ~v)
pos = np.argmax(v_ma * l)
print(f"Max consecutive price limits: {l[pos]}, starting from index {s[pos]}: {a[s[pos]]}.")Here, the mask array serves two purposes: it prevents v == False data from participating in the calculation (via v_ma * l) while preserving their order (indices). This ensures that when we call argmax, the returned index corresponds correctly to the positions in v, s, and l.
We created v_ma as a mask array with the value:
masked_array(data=[True, --, True],
mask=[False, True, False],
fill_value=True)When multiplied by another integer array, True converts to 1, resulting in another mask array:
masked_array(data=[3, --, 5],
mask=[False, True, False],
fill_value=True)When argmax is applied to a mask array, it ignores elements where mask is True but preserves their positions. Thus, the final result pos is 2, corresponding to values in v, s, and l as: True, 6, and 5.
What if we want to count the longest N-day winning streak? This is an easier task than finding price limits. However, this time we will not use a mask array:
v,s,l = find_runs(np.diff(a) > 0)
pos = np.argmax(v * l)
print(f"Longest N-day winning streak: {l[pos]}, starting from index {s[pos]}: {a[s[pos]]}.")The output is: Longest N-day winning streak is 6, starting from index 5: 20.5.
The key here is that when Numpy performs multiplication, True is treated as 1 and False as 0. The multiplication result naturally eliminates parts without consecutive gains, thus not interfering with the argmax calculation.
Of course, using a mask array might be semantically clearer, even if it is slightly slower. Correctness and readability are often more important.
Calculating Streaks in Connor's RSI
Connor's RSI (Connor's Relative Strength Index) is a technical analysis indicator developed by Nirvana Systems as an improved version of the traditional Relative Strength Index (RSI). The main difference between Connor's RSI and traditional RSI is that it considers the number of consecutive days of price increases or decreases, known as "winning streaks" and "losing streaks." This consideration allows Connor's RSI to better reflect the strength of market trends.
After introducing the find_runs function, calculating streaks becomes very simple.
def streaks(close):
result = []
conds = [close[1:]>close[:-1], close[1:]<close[:-1]]
flags = np.select(conds, [1, -1], 0)
v, _, l = find_runs(flags)
for i in range(len(v)):
if v[i] == 0:
result.extend([0] * l[i])
else:
result.extend([v[i] * x for x in range(1, (l[i] + 1))])
return np.insert(result, 0, 0)This code first divides the price series into three sub-series: rising, falling, and flat. It then calculates the number of consecutive rising or falling days for each sub-series and merges the results into a new array. In streaks, consecutive rising days are represented by positive numbers, and consecutive falling days by negative numbers. In line 5, np.select converts the condition array into a sequence of [1, 0, -1]. Subsequent multiplication yields the correct number of consecutive rising (or falling) days.
Outlier Clipping Using Median Absolute Deviation (MAD)
In factor analysis, we often need to clip outliers to reduce the impact of extreme values. The Median Absolute Deviation (MAD) method is a common approach, determining outliers by calculating the median and absolute deviation of the data.
First, we must introduce the concept of Median Absolute Deviation:
$$MAD = median(|X_i - median(X)|)$$
To make MAD a consistent estimator with the standard deviation $\sigma$, i.e.,
$$\hat{\sigma} = k \cdot MAD$$
Here, $k$ is a proportionality constant. If the distribution is normal, we can calculate: $$ k = \frac{1}{\Phi^{-1}(\frac{3}{4})} \approx 1.4826 $$
Based on this $k$ value, taking 3 times approximates 5.
When performing outlier clipping on multiple assets simultaneously, we can use the following method to achieve vectorized parallel operations:
def mad_clip(df: Union[NDArray, pd.DataFrame], k: int = 3, axis=1):
"""Outlier clipping using MAD 3x truncation method
Args:
df: Input data, requiring date index, asset names as columns, and cell values as factors (wide format)
k: Truncation multiplier.
axis: Truncation direction
"""
med = np.median(df, axis=axis).reshape(df.shape[0], -1)
mad = np.median(np.abs(df - med), axis=axis)
return np.clip(df.T, med.flatten() - k * 1.4826 * mad,
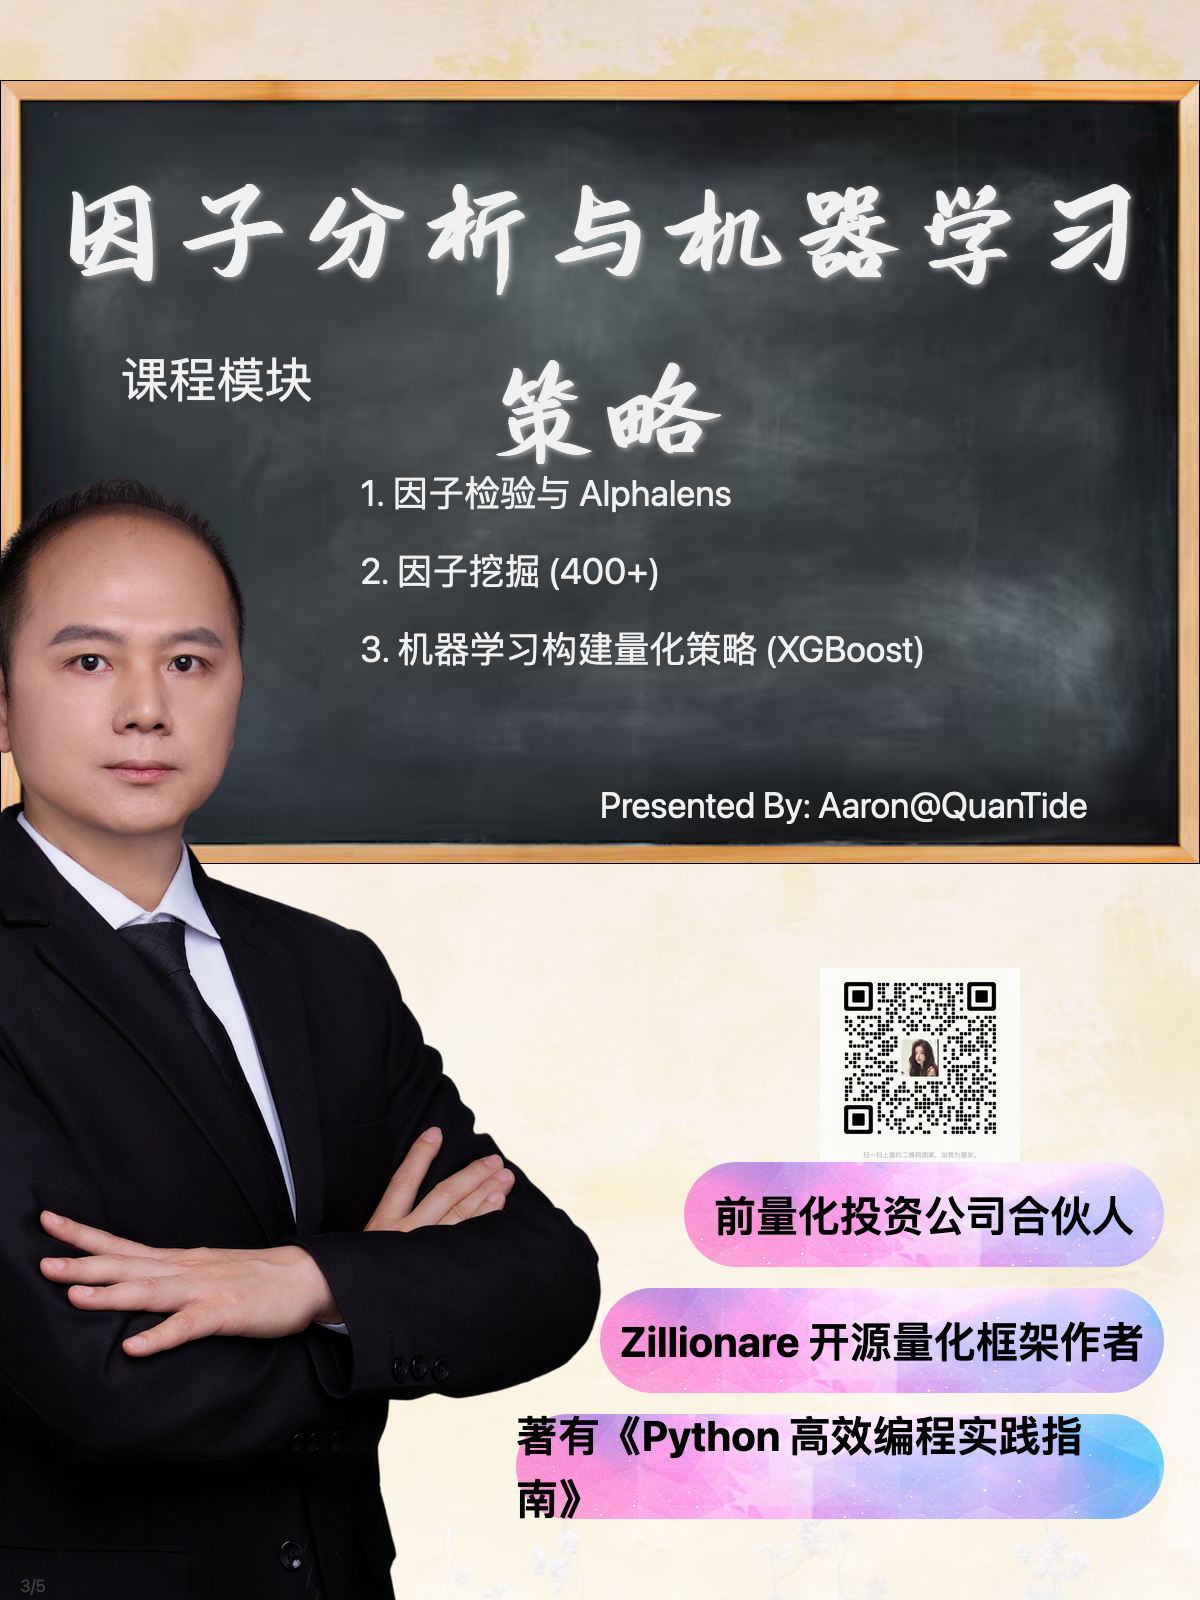
med.flatten() + k * mad).TCourse: Factor Investing and Machine Learning Strategies
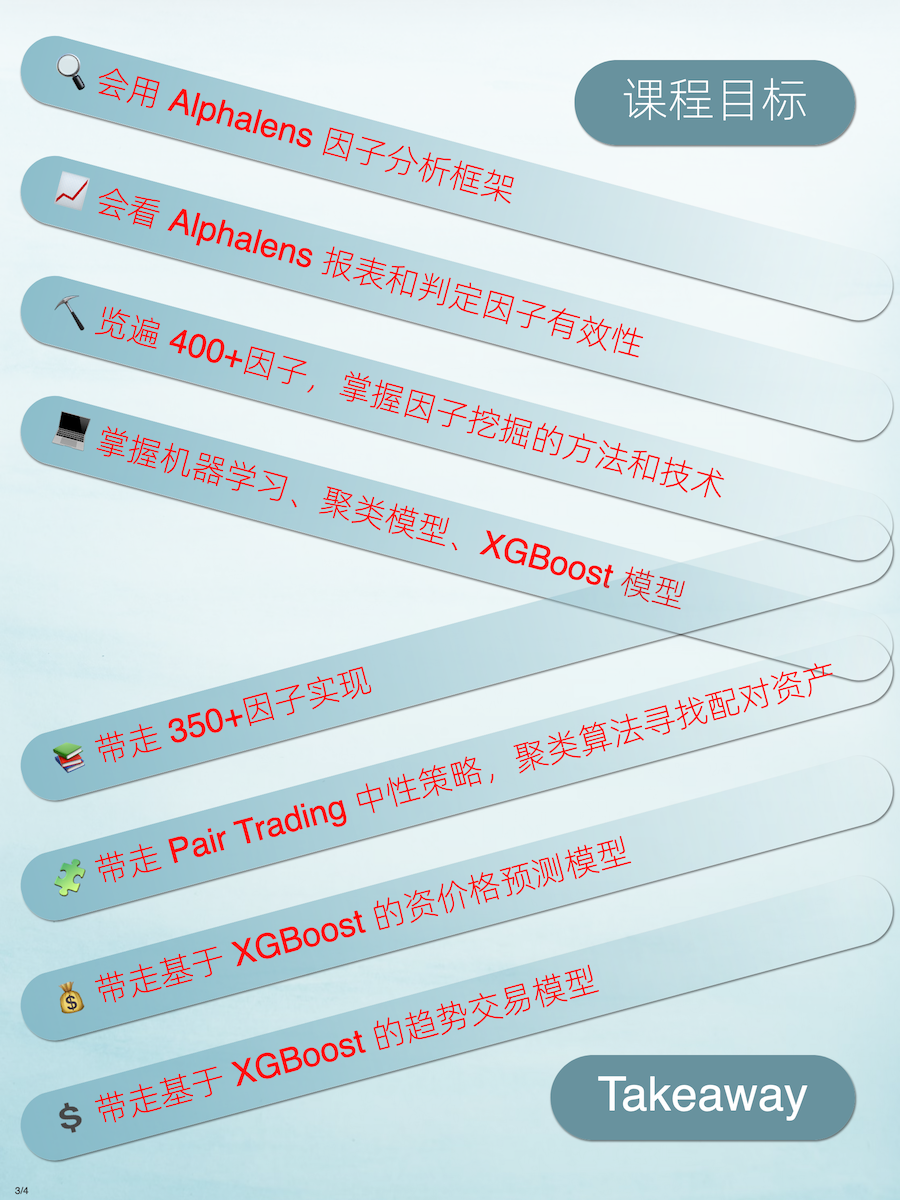
Clear Goals, Strong Sense of Achievement
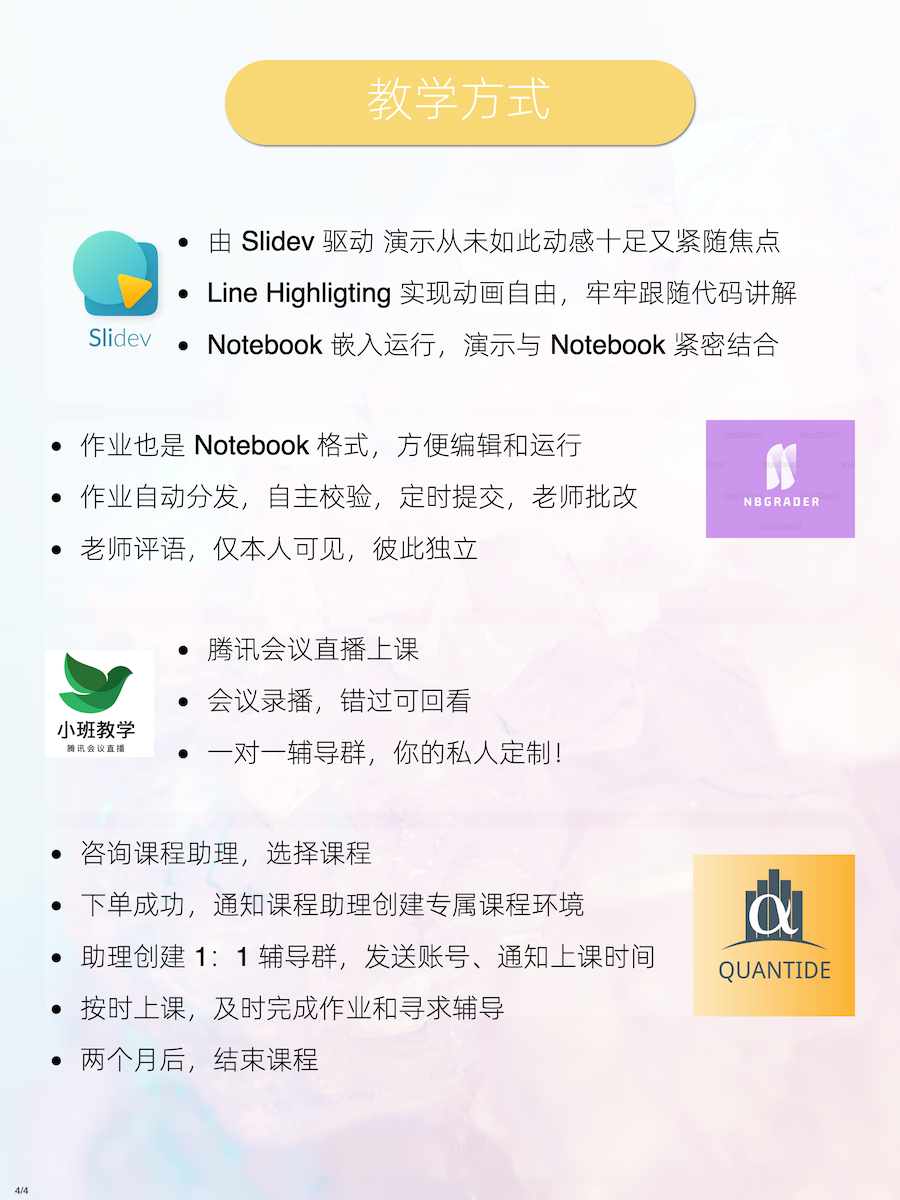
Why Choose QuanTide Courses?